 Alex
04d358ab69
In store mode every user turn chained onto the previous response, so the
provider's stored transcript grew without bound (measured: 889k prompt
tokens for a 37k-token saved history) while every local guard, the
compression pipeline included, measured the saved history. Each chained
tool round also re-sent the system message, which the server appends rather
than dedupes, and a saved compression point was applied exactly once, in the
turn that made it.

Chaining is now bounded. A turn starts from the saved history when the
previous turn's reported prompt reached the chain budget (default: the
model's context window), when the conversation was compressed after that
turn was produced, or when OPENAI_RESPONSES_CHAIN_ACROSS_TURNS is off.
Chained rounds omit an unchanged system head (hash carried in the persisted
Responses state). truncation="auto" is available behind a setting as a
backstop against a chain that outgrows the model's window.

Compression: a saved point is applied at every turn start; the threshold
counts the summary plus the queries after the point instead of the raw
history; re-compression summarises only the tail on top of the last point;
the mid-execution path marks itself persisted and resets the provider chain
so the rebuilt messages are the context; an empty summary is rejected; the
visible "[Context Compression Summary]" rows are no longer replayed as
history; appending the same point twice is a no-op.

Cache hints: a per-user prompt_cache_key and an optional
prompt_cache_retention on Responses API calls.

Measured on Azure with the same client shape as production (stateless
OpenAI client, server-side tools, PDF part): tokens billed on the sixth turn
fell from 58k to 35k, tool rounds add tens of tokens instead of ~2.8k, the
turn after a compression reused the saved summary in under two seconds
instead of re-summarising, and the round after a mid-execution compression
started from the compressed context instead of the full stored transcript.
DocsGPT 🦖
Private AI for agents, assistants and enterprise search
DocsGPT is an open-source AI platform for building intelligent agents and assistants. Features Agent Builder, deep research tools, document analysis (PDF, Office, web content, and audio), Multi-model support (choose your provider or run locally), and rich API connectivity for agents with actionable tools and integrations. Deploy anywhere with complete privacy control.


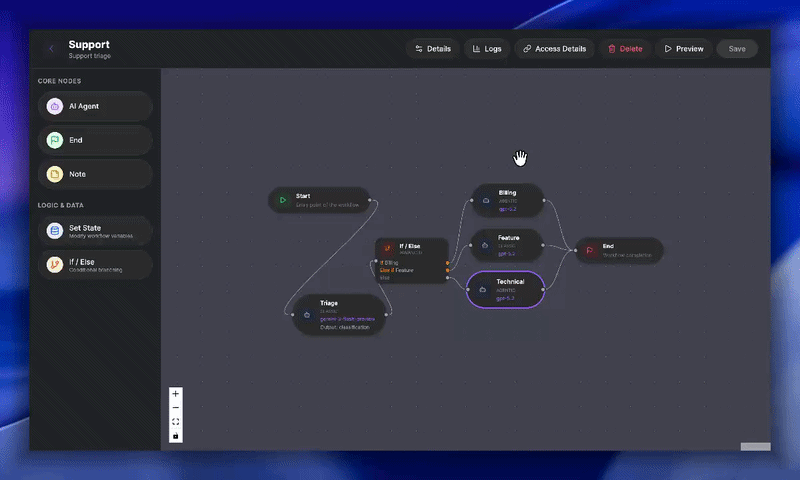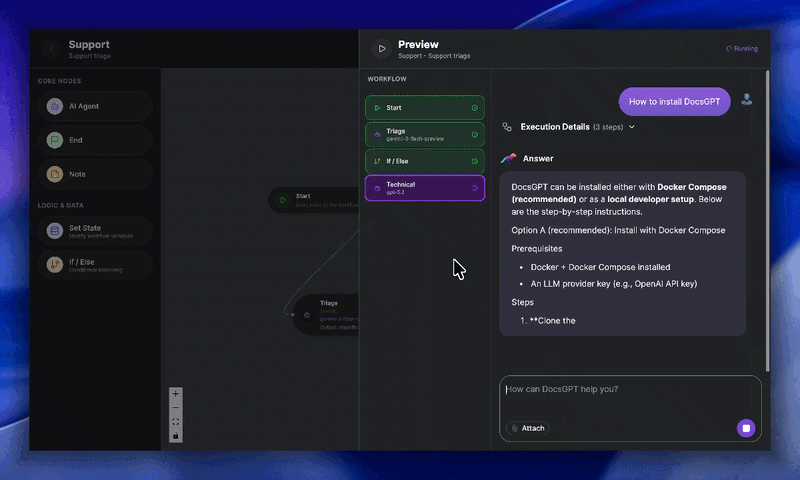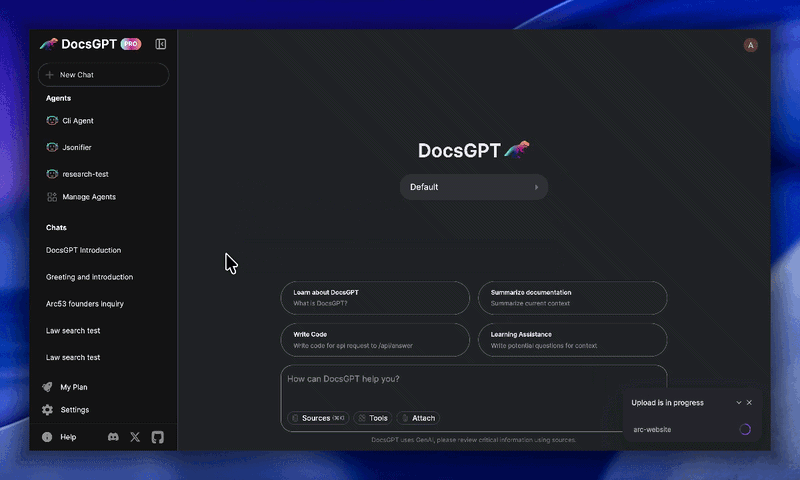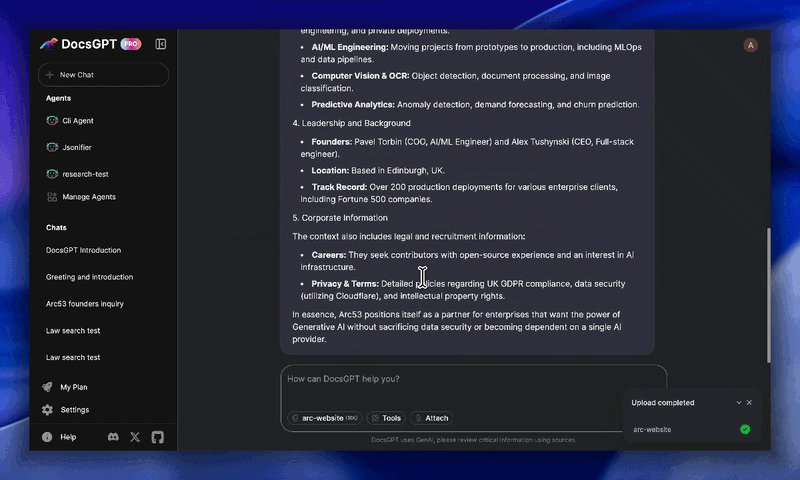
Key Features:
- 🗂️ Wide Format Support: Reads PDF, DOCX, CSV, XLSX, EPUB, MD, RST, HTML, MDX, JSON, PPTX, images, and audio files such as MP3, WAV, M4A, OGG, and WebM.
- 🎙️ Speech Workflows: Record voice input into chat, transcribe audio on the backend, and ingest meeting recordings or voice notes as searchable knowledge.
- 🌐 Web & Data Integration: Ingests from URLs, sitemaps, Reddit, GitHub and web crawlers.
- ✅ Reliable Answers: Get accurate, hallucination-free responses with source citations viewable in a clean UI.
- 🔑 Streamlined API Keys: Generate keys linked to your settings, documents, and models, simplifying chatbot and integration setup.
- 🔗 Actionable Tooling: Connect to APIs, tools, and other services to enable LLM actions.
- 🧩 Pre-built Integrations: Use readily available HTML/React chat widgets, search tools, Discord/Telegram bots, and more.
- 🔌 Flexible Deployment: Works with major LLMs (OpenAI, Google, Anthropic) and local models (Ollama, llama_cpp).
- 🏢 Secure & Scalable: Run privately and securely with Kubernetes support, designed for enterprise-grade reliability.
Roadmap
- Agent Workflow Builder with conditional nodes ( February 2026 )
- Research mode ( March 2026 )
- SharePoint & Confluence connectors ( March – April 2026 )
- Postgres migration for user data ( April 2026 )
- OpenTelemetry observability ( April 2026 )
- Bring Your Own Model (BYOM) ( April 2026 )
- Agent scheduling (RedBeat-backed) ( April 2026 )
- Notifications & conversation search ( May 2026 )
- Analytics & logs revamp with per-agent attribution ( June 2026 )
- OIDC / SSO login with SCIM provisioning & groups ( June 2026 )
- Admin dashboard & role-based access control (RBAC) ( June 2026 )
- Agent import / export ( June 2026 )
- Teams with team-scoped sharing & roles ( June 2026 )
You can find our full roadmap here. Please don't hesitate to contribute or create issues, it helps us improve DocsGPT!
Production Support / Help for Companies:
We're eager to provide personalized assistance when deploying your DocsGPT to a live environment.
Join the Lighthouse Program 🌟
Calling all developers and GenAI innovators! The DocsGPT Lighthouse Program connects technical leaders actively deploying or extending DocsGPT in real-world scenarios. Collaborate directly with our team to shape the roadmap, access priority support, and build enterprise-ready solutions with exclusive community insights.
QuickStart
Note
Make sure you have Docker installed
A more detailed Quickstart is available in our documentation
-
Clone the repository:
git clone https://github.com/arc53/DocsGPT.git
cd DocsGPT
For macOS and Linux:
-
Run the setup script:
./setup.sh
For Windows:
-
Run the PowerShell setup script:
PowerShell -ExecutionPolicy Bypass -File .\setup.ps1
Either script will guide you through setting up DocsGPT. Five options are available: using the public API, running locally, connecting to a local inference engine, using a cloud API provider, or building the docker image locally. The scripts will automatically configure your .env file and handle necessary downloads and installations based on your chosen option.
Navigate to http://localhost:5173/
To stop DocsGPT, open a terminal in the DocsGPT directory and run:
docker compose -f deployment/docker-compose.yaml down
(or use the specific docker compose down command shown after running the setup script).
Note
For development environment setup instructions, please refer to the Development Environment Guide.
Contributing
Please refer to the CONTRIBUTING.md file for information about how to get involved. We welcome issues, questions, and pull requests.
Architecture
Project Structure
-
Application - Backend Flask application.
-
Extensions - Integrations and widgets (e.g., Chatwoot, React widget).
-
Scripts - Miscellaneous utility scripts.
Code Of Conduct
We as members, contributors, and leaders, pledge to make participation in our community a harassment-free experience for everyone, regardless of age, body size, visible or invisible disability, ethnicity, sex characteristics, gender identity and expression, level of experience, education, socio-economic status, nationality, personal appearance, race, religion, or sexual identity and orientation. Please refer to the CODE_OF_CONDUCT.md file for more information about contributing.
Many Thanks To Our Contributors⚡
License
The source code license is MIT, as described in the LICENSE file.
This project is supported by:
