 Alex
795e39a6bc
Source access control
---------------------
`active_docs` is client-supplied and reached the retriever unchecked, and the
retriever queries `WHERE source_id = <id>` with no owner predicate — so any
caller could pass any source id to /stream or /api/answer and have another
tenant's documents quoted back, while /api/sources/<id>/search correctly
refused the same id. Gate it through `can_access`, the helper the guarded
endpoints already use, and filter `self.source` down to the authorized set.
Fails closed: no principal, or a check that errors, drops the source.

Three sibling paths had the same gap:

- workflow agent nodes: `AgentNodeConfig.sources` is written verbatim from
  client JSON at save time and nothing validated it, so a node could name any
  tenant's source. Gate against the workflow owner, so shared workflows keep
  reading their owner's sources like shared agents do.
- /api/share: `_resolve_source_pg_id` resolved any id with no ownership
  predicate and baked it into the agent the share creates; /api/search then
  searched it. Authorize before attaching.
- search_service: re-resolve the ids stored on an agent row instead of
  trusting them, so a row written by any future path with the same gap cannot
  be read back.

Team grantees previously lost their source's retrieval config: the post-check
read was still owner-scoped, so it missed and fell back to defaults (an
`agentic_tool` source was bulk-prefetched for every grantee). Read unscoped
after `can_access` passes.

Retrieval
---------
`PGVectorStore._ensure_table_exists` created an IVFFlat index on the empty
table it had just created. IVFFlat computes centroids at build time, so those
centroids were random, and combined with the `source_id` post-filter a source
with hundreds of embedded chunks returned zero rows — retrieval reported no
documents, the model answered from memory, and nothing was logged. Stop
creating the index (exact search is correct and fast well past the sizes most
deployments reach); raise `ivfflat.probes` to sqrt(lists) where an index still
exists; and re-run a short indexed search exactly, since post-filtering means
no index setting can guarantee a full result. `graphrag` had the same
empty-table index with no fallback at all.

Also: bound `chunks` to 0-500 on both the request and agent paths (0 still
means "skip retrieval"), let a source's configured `retrieval.chunks` outrank
the request body, and cap ClassicRAG's per-source floor at
max(top_k, n_sources) so attaching sources cannot inflate the result set.

Silent failures
---------------
An empty retrieval was invisible to both the model and the client: the `source`
event was suppressed when the list was empty, so "searched and found nothing"
looked identical to "no source attached", and the prompt said nothing at all.
Emit the event always, and tell the model when a search ran and returned
nothing. A file that parses to nothing now fails ingest with a message naming
the cause instead of storing an embedding of the empty string. `score_threshold`
returns warnings when the active store or retriever cannot honour it.

Prompt structure
----------------
Retrieved documents move from the system prompt into the user turn, with the
injection guard restated next to them: they change every turn (defeating prefix
caching), they are third-party text that should not carry system authority, and
routing them through the query budget makes them truncatable rather than
silently crowding it out. Documents are shed lowest-ranked-first before the
question is touched.

The six chat presets (3 tones x 2 retrieval modes) differed only in their
Answering section; they are now composed from single-source fragments at load
time, not through Jinja inheritance, which would have opened a file-read
surface in the template sandbox and broken the tool-prefetch parser. Per-tool
guidance moves out of the prompt into tool schemas, so it travels with the tool
and cannot render when the tool is absent. A plain-text custom prompt is staged
as a persona value inside the skeleton instead of replacing it wholesale — it
used to silently lose the injection guard, platform block, memory and
attachments, and its braces are now inert.

Other fixes
-----------
- agents/base: an oversized system prompt drove the query budget negative and
  dispatched a full-price request with an empty question; raise instead.
- llm/anthropic: migrate off the retired Text Completions API. It flattened
  history to first+last message and ignored tools entirely. Adds the missing
  Anthropic handler, without which every tool call was silently dropped.
- sources/upload: `sitemap` had no branch, so every sitemap ingest died on a
  TypeError; `validate_url` now rejects a falsy URL cleanly.
- workflow nodes: retrieved documents never reached the node agent, so a
  classic node with a source and an ordinary prompt answered "I have no
  documents" while the run reported completed.
- parser/bulk: copy the metadata dict, or every chunk reports the last chunk's
  token_count.
- crawler_loader: carry the page title, or citations render the whole chunk
  body as the label.
DocsGPT 🦖
Private AI for agents, assistants and enterprise search
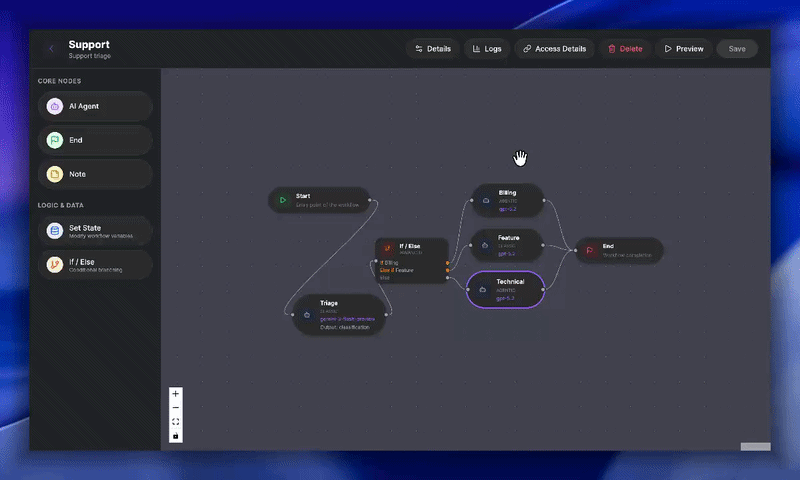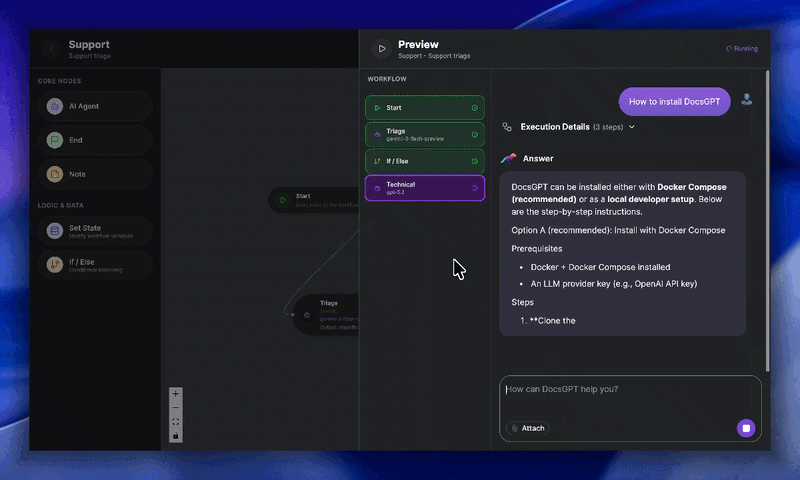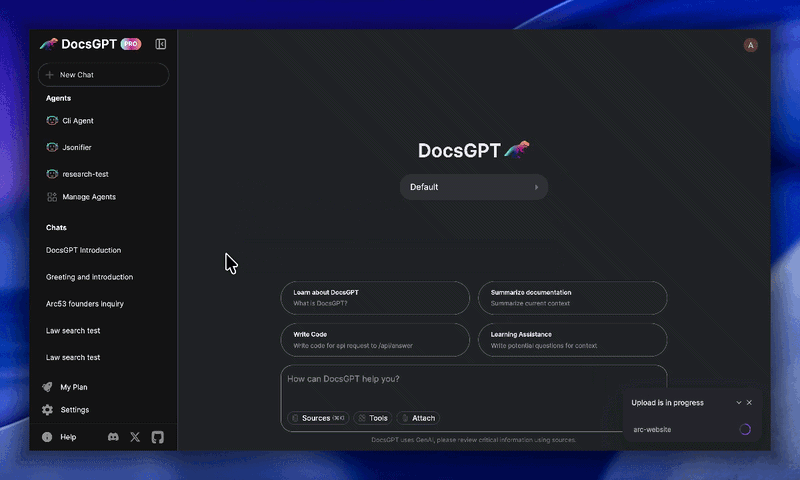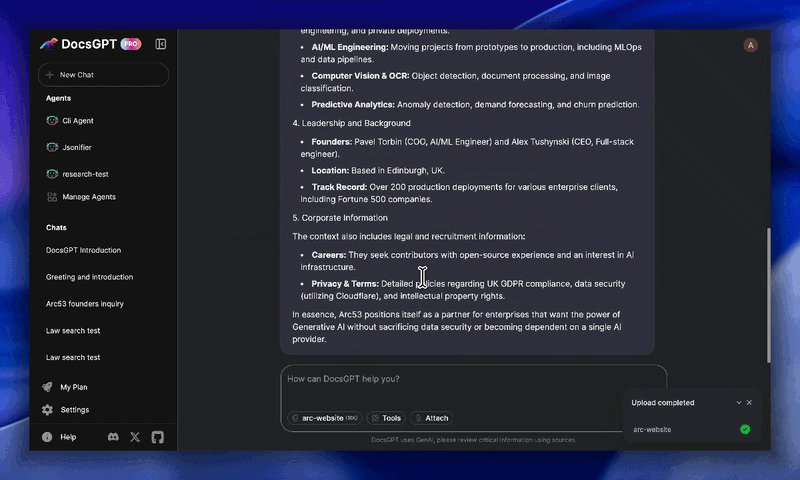
DocsGPT is an open-source AI platform for building intelligent agents and assistants. Features Agent Builder, deep research tools, document analysis (PDF, Office, web content, and audio), Multi-model support (choose your provider or run locally), and rich API connectivity for agents with actionable tools and integrations. Deploy anywhere with complete privacy control.


Key Features:
- 🗂️ Wide Format Support: Reads PDF, DOCX, CSV, XLSX, EPUB, MD, RST, HTML, MDX, JSON, PPTX, images, and audio files such as MP3, WAV, M4A, OGG, and WebM.
- 🎙️ Speech Workflows: Record voice input into chat, transcribe audio on the backend, and ingest meeting recordings or voice notes as searchable knowledge.
- 🌐 Web & Data Integration: Ingests from URLs, sitemaps, Reddit, GitHub and web crawlers.
- ✅ Reliable Answers: Get accurate, hallucination-free responses with source citations viewable in a clean UI.
- 🔑 Streamlined API Keys: Generate keys linked to your settings, documents, and models, simplifying chatbot and integration setup.
- 🔗 Actionable Tooling: Connect to APIs, tools, and other services to enable LLM actions.
- 🧩 Pre-built Integrations: Use readily available HTML/React chat widgets, search tools, Discord/Telegram bots, and more.
- 🔌 Flexible Deployment: Works with major LLMs (OpenAI, Google, Anthropic) and local models (Ollama, llama_cpp).
- 🏢 Secure & Scalable: Run privately and securely with Kubernetes support, designed for enterprise-grade reliability.
Roadmap
- Agent Workflow Builder with conditional nodes ( February 2026 )
- Research mode ( March 2026 )
- SharePoint & Confluence connectors ( March – April 2026 )
- Postgres migration for user data ( April 2026 )
- OpenTelemetry observability ( April 2026 )
- Bring Your Own Model (BYOM) ( April 2026 )
- Agent scheduling (RedBeat-backed) ( April 2026 )
- Notifications & conversation search ( May 2026 )
- Analytics & logs revamp with per-agent attribution ( June 2026 )
- OIDC / SSO login with SCIM provisioning & groups ( June 2026 )
- Admin dashboard & role-based access control (RBAC) ( June 2026 )
- Agent import / export ( June 2026 )
- Teams with team-scoped sharing & roles ( June 2026 )
You can find our full roadmap here. Please don't hesitate to contribute or create issues, it helps us improve DocsGPT!
Production Support / Help for Companies:
We're eager to provide personalized assistance when deploying your DocsGPT to a live environment.
Join the Lighthouse Program 🌟
Calling all developers and GenAI innovators! The DocsGPT Lighthouse Program connects technical leaders actively deploying or extending DocsGPT in real-world scenarios. Collaborate directly with our team to shape the roadmap, access priority support, and build enterprise-ready solutions with exclusive community insights.
QuickStart
Note
Make sure you have Docker installed
A more detailed Quickstart is available in our documentation
-
Clone the repository:
git clone https://github.com/arc53/DocsGPT.git
cd DocsGPT
For macOS and Linux:
-
Run the setup script:
./setup.sh
For Windows:
-
Run the PowerShell setup script:
PowerShell -ExecutionPolicy Bypass -File .\setup.ps1
Either script will guide you through setting up DocsGPT. Five options are available: using the public API, running locally, connecting to a local inference engine, using a cloud API provider, or building the docker image locally. The scripts will automatically configure your .env file and handle necessary downloads and installations based on your chosen option.
Navigate to http://localhost:5173/
To stop DocsGPT, open a terminal in the DocsGPT directory and run:
docker compose -f deployment/docker-compose.yaml down
(or use the specific docker compose down command shown after running the setup script).
Note
For development environment setup instructions, please refer to the Development Environment Guide.
Contributing
Please refer to the CONTRIBUTING.md file for information about how to get involved. We welcome issues, questions, and pull requests.
Architecture
Project Structure
-
Application - Backend Flask application.
-
Extensions - Integrations and widgets (e.g., Chatwoot, React widget).
-
Scripts - Miscellaneous utility scripts.
Code Of Conduct
We as members, contributors, and leaders, pledge to make participation in our community a harassment-free experience for everyone, regardless of age, body size, visible or invisible disability, ethnicity, sex characteristics, gender identity and expression, level of experience, education, socio-economic status, nationality, personal appearance, race, religion, or sexual identity and orientation. Please refer to the CODE_OF_CONDUCT.md file for more information about contributing.
Many Thanks To Our Contributors⚡
License
The source code license is MIT, as described in the LICENSE file.
This project is supported by:
